


Enterprise-Grade Compute for AI Innovation
Centralized, high-performance Enterprise-grade AI compute infrastructure — built on 4× NVIDIA H100 GPUs, dual Intel Xeon Platinum processors, and Unity XT 680 - 150 TB SAN storage to accelerate AI model development, training, inference, data analytics, and advanced research at scale.
Why This Infrastructure
Train Without Bottlenecks
Four NVIDIA H100 GPUs with 94GB memory each — 376GB of GPU memory in total — give large-scale training and fine-tuning workloads room to run without resource contention.
Enterprise Compute at the Core
Dual Intel Xeon Platinum 8568Y+ processors (96 cores / 192 threads) and 1,024GB of DDR5 RAM handle the CPU-side data processing, orchestration, and multi-user workloads that sit alongside GPU compute.
Storage That Keeps Up
Dell Unity SAN storage — 130TB usable, with 20TB SSD cache, provides low-latency, shared access across workloads, so data pipelines and model training run in parallel without I/O contention.
Centrally Managed, Securely Hosted
Securely Hosted with VPN-based access, user-specific VM isolation, and continuous monitoring, enterprise-grade management without individual infrastructure investment.
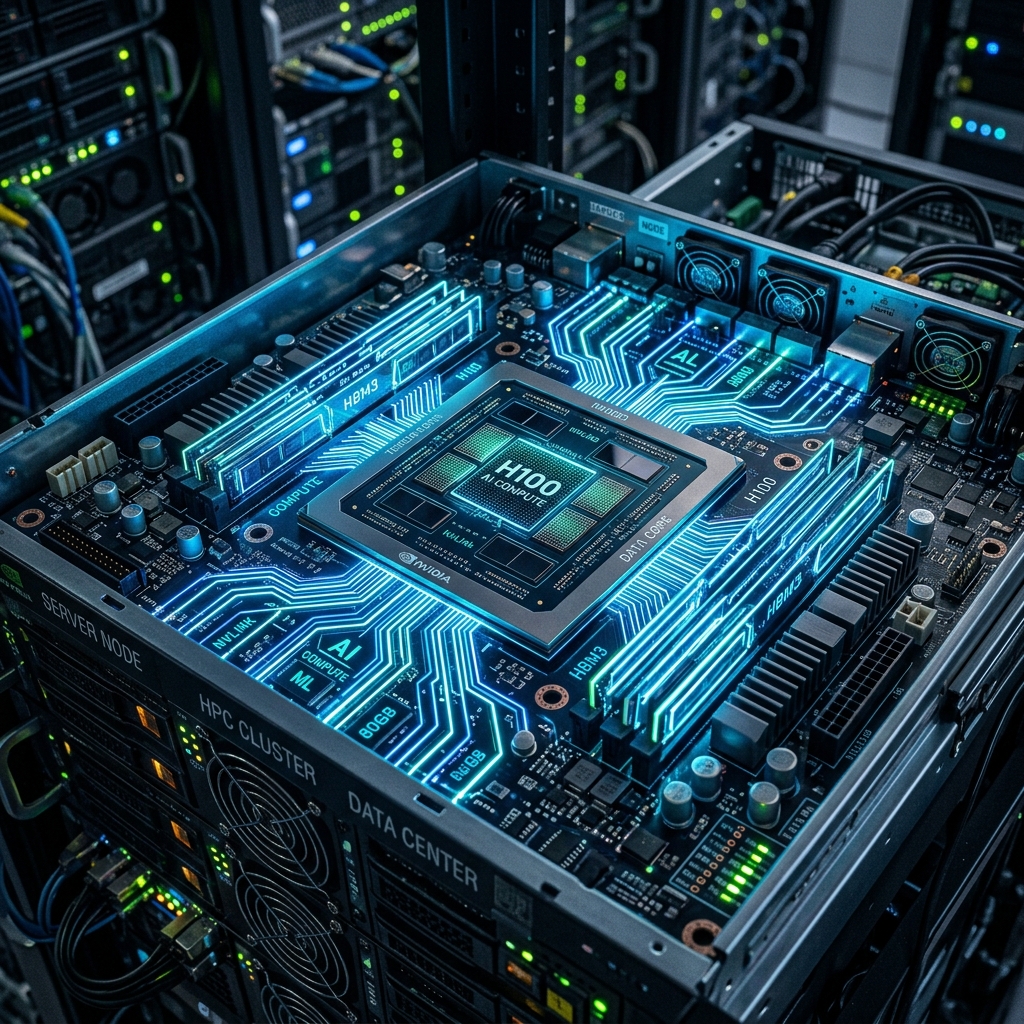
Powered by NVIDIA H100
Each GPU is built on the NVIDIA Hopper architecture, engineered for large-scale AI and HPC workloads:
Fourth-gen Tensor Cores + Transformer Engine — accelerates transformer-based model training and inference, with FP8 precision purpose-built for large language models.
Up to 4X faster AI training on GPT-3–class models compared to the prior generation.
Up to 30X faster inference on the largest models, with the lowest latency.
NVLink interconnect at up to 900GB/s GPU-to-GPU bandwidth, so multi-GPU jobs scale efficiently rather than bottlenecking on data transfer.
High-bandwidth memory — up to 3.35TB/s memory bandwidth per GPU, built to move large datasets without stalling compute.
Technical Specifications
Secure by Design
- VPN-based remote access network
- User-specific VM isolation and restricted port access (SSH, HTTPS, HTTP)
- Firewall controls, malware/endpoint protection, and continuous utilization monitoring
- End users are expected to stay alert to application-level malware and unauthorized proxy usage to help safeguard the shared infrastructure
- Periodic review of user access and VM allocation
Who Can Access
Access is available to students, faculty, and researchers for academic and AI/ML work, startups for prototyping and scaling AI products, and Government departments for data and governance needs, with priority given to eligible startups.
Five critical workloads. One unified platform.
From large-scale model training to real-time inference — each workload is covered in the hardware and software layer.
LLM Training & Fine Tuning
Dual H100s connected over NVLink handle large-scale model training, fine-tuning, and batch inference workloads without bottlenecking on GPU interconnect.
Data Engineering & Analytics
Oracle Data Integrator moves and orchestrates enterprise data into training-ready pipelines. Unity XT 680 provides low-latency shared storage across workloads.
Development Application Hosting
Build, deploy, and scale AI-powered applications, APIs, and intelligent services with seamless progression from prototyping and testing to production-ready deployment.
Computer Vision & Simulation
High-throughput GPU compute for video analytics, sensor fusion, robotics simulation, and visual ML pipelines common in deep-tech hardware startups.
Unified AI Infrastructure
Compute, storage, software and enterprise support in a single procurement — suited for university labs, R&D centres, and shared innovation infrastructure.
Ready to Build?
Access AI Computer →
Tamil Nadu Technology Hub (iTNT)
-
3rd Floor, Sir C V Raman Science Block, Anna University Campus, Kotturpuram, Chennai, Tamil Nadu, India – 600025 044 29887718 | office[at]tnthub[dot]org